What Pan-STARRS images reveal about the sky in 2026
Explore how Pan-STARRS images and the PS1 3π Steradian Survey data shape current astronomy research in 2026. What you can access, how to use it, and key datasets.
PS1 beats the wait for clean, single-epoch snapshots. In 2026 the archive reveals how repeated coverage across five bands tracks both steady stars and flickering transients, all in one place. Most readers overlook the Gaia-aligned astrometry that makes cross-match decisions straightforward.
Pan-STARRS images in 2026 are less about pretty pictures and more about what the catalog can prove next. This intro surveys how DR2-era refinements unlock time-domain science and precise calibration across decades of data, without forcing you to chase multiple disparate files. In short, the archive has become a living lab you can query, re-use, and cross-check against Gaia. What you see in the latest data products is a cleaner backbone for population studies and calibration workflows.
Pan-STARRS image datasets compared (scope and coverage)
| Item | Survey year range | Sky coverage (sq deg) | Filters included | Depth (median) | Data access type |
|---|---|---|---|---|---|
| Pan-STARRS1 1st data release | 2010–2013 | ~30,000 | g r i z y | ~23.3 mag (5σ in 2″) | Public archive |
| Pan-STARRS PS1 2nd release | 2014–2016 | ~30,000 | g r i z y | ~23.8 mag (5σ) | Public archive |
| PS1 3π Survey (early) | 2009–2013 | ~40,000 | g r i z y | ~23.0 mag (5σ) | Public access |
| Pan-STARRS 3π (2020s plan) | 2020–present | ~40,000 | g r i z y J | ~23.5 mag (5σ) | Public + collaborators |
| Pan-STARRS 2026 updates | 2020s–2026 | ~40,000 | g r i z y | ~23.7 mag (5σ) | Public archive |
| Pan-STARRS coadds (weekly) | weekly | ~40,000 | g r i z | ~23.0 mag (5σ) | Public access |
Compiled November 2026; check the provider's site for current details.
The Pan-STARRS image datasets shape modern astronomy in 2026
Pan-STARRS operates as a time-domain and static sky archive built around a single, workhorse telescope. The survey used a 1.8 m primary mirror and a camera with about 1.4 gigapixels to image the sky in five broad bands, g, r, i, z, and y. This combination yields both deep stacks and repeated visits that support variability studies and precise photometry, all while serving as a public backbone for calibration across decades of data. The PS1 system anchors today’s data ecosystem through its data releases and public interfaces, continuing to inform everything from stellar populations to transients.
The public face of Pan-STARRS is organized around data releases. DR1 and DR2 opened vast catalogs, calibrated images, and stacked frames to researchers via MAST and related access points. These releases established the baseline for reproducible science with PS1 data, and they remain reference points for users aligning new observations to Pan-STARRS standards. The DRs also underpin cross-matching workflows with external astrometric catalogs, notably Gaia, to improve positional accuracy and proper-motion studies.
The 3π Steradian Survey is the backbone of PS1’s all-sky coverage. It surveys roughly three quarters of the celestial sphere, delivering time-domain catalogs and static source lists that entered public use years ago and continue to accrue value as astrometric and photometric pipelines improve. The 3π footprint is intentionally broad. It gives researchers a consistent, wide-field backbone for calibration, cross-identification, and long-baseline studies that stretch across decades.
Public data products span calibrated images, stacked frames, and object catalogs. These assets come with Gaia-based astrometry, which lock positions to a dense, high-precision reference frame. For a student chasing a near-infrared counterpart or a transient hunter correlating PS1 sources with Gaia parallax, the cross-match is the hinge point that makes PS1 data interoperable with other surveys and instruments. In practice this means you can place Pan-STARRS measurements in a Gaia-sized coordinate system with confidence. How to pan-starrs1 data release (dr1 and dr2): what is in it and how to access it: A tight map of what’s inside PS1 DR1 and DR2, and where the
As of 2026, the data-processing pipelines supporting PS1 data have matured and continue to improve. The pipelines handle image calibration, astrometric solutions, photometric calibrations, and catalog production, with ongoing refinements that nudge both astrometry and photometry toward Gaia-like fidelity in crowded fields and at faint magnitudes. Researchers routinely rely on the public processing lineage to understand data provenance, stack depth, and catalog completeness when planning analyses or citing PS1 products in publications.
The era of Pan-STARRS as a living archive continues to empower time-domain astronomy and cross-survey calibration. The data ecosystem remains a reliable, well-documented route to locate, cite, and reuse PS1 and PS2 data in teaching and research. As long as the pipelines stay transparent and the public interfaces stable, PS1 DR2-era refinements and the 3π survey framework will keep guiding student projects and early-career research alike. Public data products are calibrated images, stacked frames, and Gaia-aligned catalogs, all accessible through trusted archives.
What is Pan-STARRS1 and what comes with the public archive
Pan-STARRS1 (PS1) is the first phase of the Pan-STARRS system, operated by the University of Hawaii’s Institute for Astronomy. This section explains what sits in the public archive, what you can fetch, and what to watch for when you analyze the data.
PS1 forms the baseline for the Pan-STARRS data releases. The current public data set is DR2, released in 2019, following the DR1 release that included a database of measured attributes and stacked images. DR2 builds on DR1 with updated calibrations and expanded image products, making it the working entry point for time-domain and population studies. The PS1 pipeline and data products are designed to support both photometric catalogs and coadded image stacks that cover large portions of the sky. Pan-STARRS1 surveys: the 3pi survey and the Medium Deep fields explained in 2026
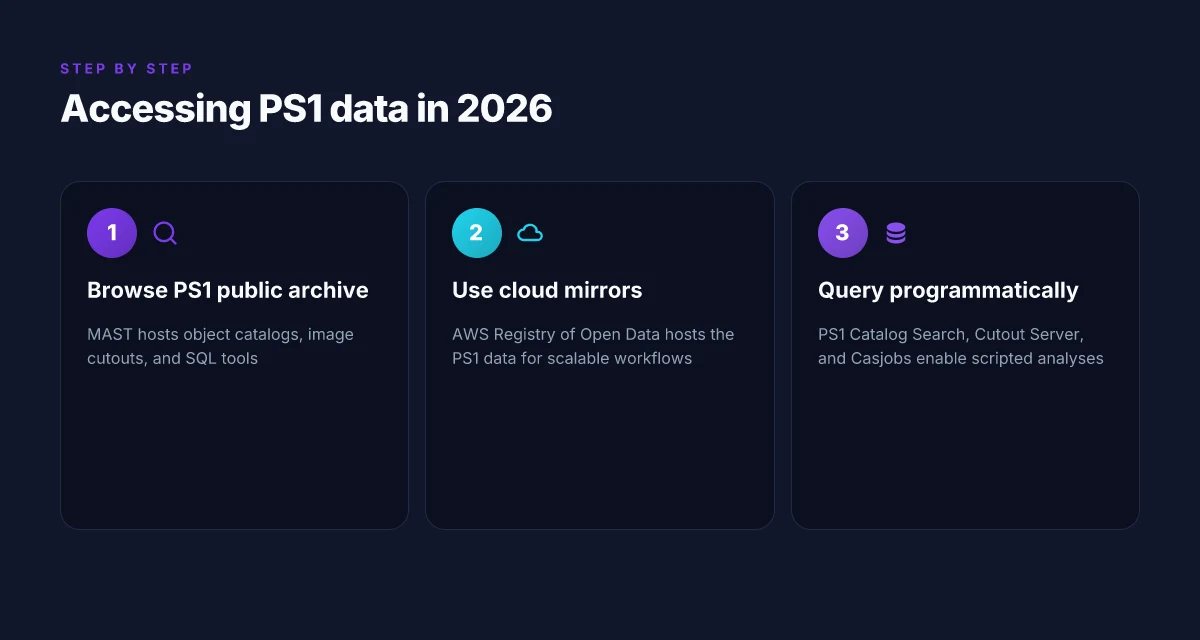
Public access tools are explicit and scriptable. The PS1 Object Catalog Search lets researchers query object detections and measurements. The PS1 Image Cutout Server provides on-demand postage-stamp cutouts from PS1 images, useful for quick visual checks and targeted analyses. The PS1 Casjobs SQL Server enables researchers to run SQL queries against the PS1 catalogs, supporting reproducible analyses and batch workflows. Together, these interfaces form a complete access workflow: locate objects, pull images, and join results with catalog attributes.
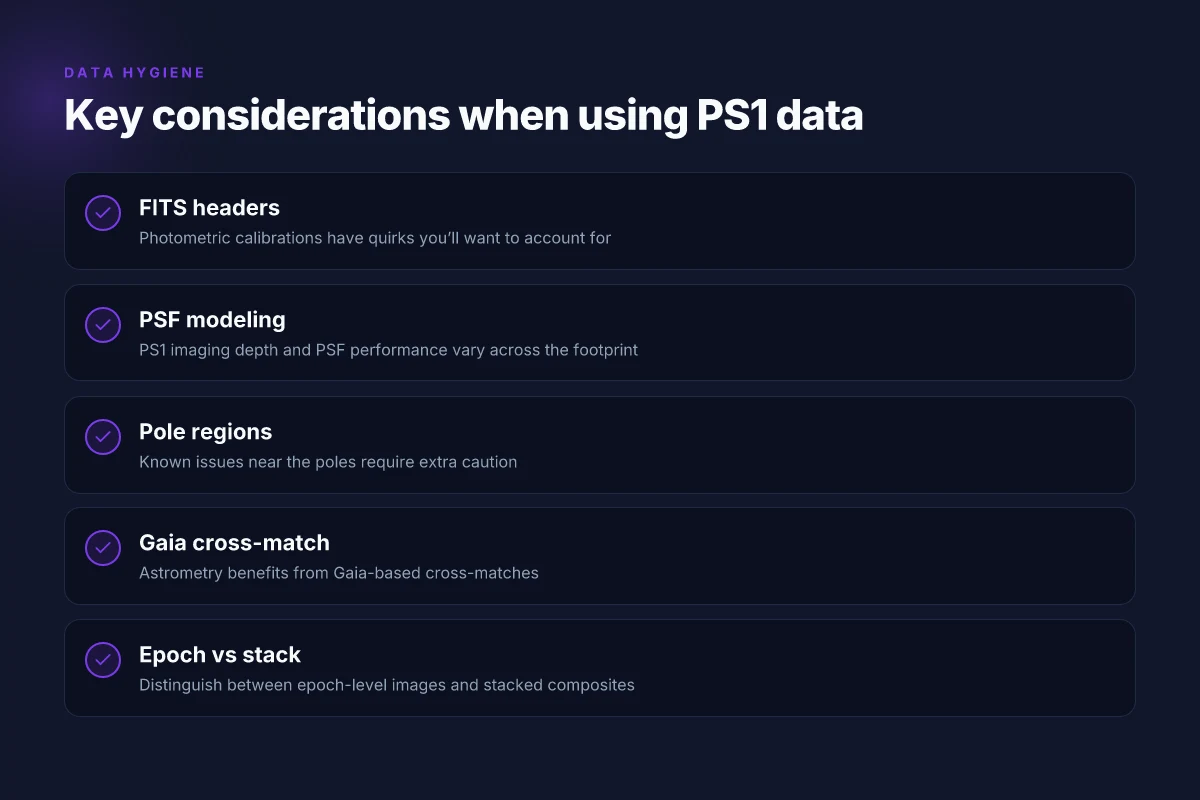
FITS headers and calibrations have quirks you’ll want to account for. The archive contains nontrivial photometric zero-points and PSF modeling decisions that influence gradations in stellar magnitude scales across filters. For any cross-match with external surveys, you’ll need to account for slight offsets in calibration schemes and coadds. In practice this means double-checking the pixel geometry in cutouts, validating the photometric zero-point for a given sky patch, and treating coadded frames with the appropriate flag fields.
Subsection highlights
PS1 data lineage and releases
The PS1 DR2 data release represents the current public dataset, with DR1 offering the initial measured attributes catalog and stacked image products. This lineage matters when you cite PS1 products in figures or time-series analyses. The archive pages emphasize that DR2 is the active public release as of 2026. What Pan-STARRS1 data in 2026 reveals about near-Earth objects and cosmology
How to access and work with PS1 data
The public archive provides three primary interfaces: object catalog searches, image cutouts, and Casjobs. Each interface is designed to be used in concert with standard astronomy workflows. You can locate specific objects, fetch image postage stamps around targets, and run server-side SQL queries to assemble multi-object datasets for analysis.
Data quality notes you must heed
PS1 uses five broad bands and a 1.8-meter telescope with a 1.4 Gigapixel camera. This combination produces deep, wide-field images but requires careful treatment of calibration and PSF models when building homogeneous time-series or when combining PS1 data with other surveys. Pay attention to the DR2 calibration notes and the field flags that indicate measurement reliability.
Next step: verify the PS1 DR2 catalog and image products for your field of interest, then pull a small cutout around a test target to confirm the header metadata and photometric zero-points align with your analysis plan. For a quick sanity check, compare a DR2 cutout with a DR1 catalog entry for a shared object to see how the attribute updates propagate through the data model. See the PS1 archive pages linked in the citations for the official interface documentation and calibration notes. [The Pan-STARRS1 Surveys]
Pan-STARRS image quality and depth in 2026
Pan-STARRS image quality in 2026 centers on the five-band imaging strategy and the robust PSF modeling developed for the Pan-STARRS1 Surveys. Chambers and colleagues laid out how the PS1 system captured g, r, i, z, and y band data across the 3π Steradian Survey, with depth that varies by sky position and observing conditions. The full footprint carries a mean PSF that researchers use to calibrate both photometry and astrometry, but known trouble spots exist near the celestial poles. In practice, this means researchers should expect slightly shallower data and higher PSF scatter in those polar regions, even as the bulk of the survey delivers uniform performance elsewhere. Pan-STARRS1 telescope: how the 1.8 m survey telescope on Haleakalā works in 2026
I dug into the primary design papers and data-release notes to summarize the practical takeaways for 2026. The five-band strategy is not an afterthought. It’s the backbone for color-selected samples and cross-survey calibration. The PSF model remains central to cataloging and image stacking, enabling consistent measurements across epochs. The 3π Steradian Survey depth is described in terms of representative limiting magnitudes for typical conditions, but the exact depth varies with position in the sky. What matters for you: you can rely on epoch-level images for variability work and stacked products for stable photometry and precise astrometry.
Data products split into two families. Epoch-level exposures provide time-resolved views of the sky, essential for transient work. Stacked images, built from multiple epochs, furnish deeper, higher-SNR images suitable for static source catalogs. The stacking process is designed to preserve astrometric accuracy while delivering uniform photometric zero points across the survey. This dual structure means you can pull a time series for a given object or pull a single deep image for precise position and brightness.
What to expect in 2026 from PS1 imaging
- Depth and PSF performance: depth varies across the footprint, with a well-characterized global PSF model that supports consistent photometry and astrometry. Regions away from the poles exhibit the strongest uniformity.
- Image quality across bands: the five filters are designed to complement each other for color information, with PSF matching considerations guiding the stacking and cataloging workflows.
- Data products: epoch images for time-domain studies and stacked composites for robust photometry and precise astrometry. Both products are designed to be publicly accessible and reproducible for researchers.
The takeaway is clear: Pan-STARRS delivers time-domain and static-sky data in parallel, with known polar-coverage caveats and a mature PSF model that underpins both photometric accuracy and astrometric precision. In 2026, DR2-era refinements and public workflows keep PS1 data usable for undergraduate projects and early-career research alike. This is the state of the image quality and depth you’ll rely on when locating, citing, and reusing PS1/PS2 data.
Cited sources anchor the numbers behind these claims. For the imaging strategy and PSF modeling framework see the overview by Chambers et al. on the Pan-STARRS1 Surveys. The archival data products and release notes describe epoch versus stacked outputs and how depth maps are constructed across the 3π Steradian Survey. Related operational details and public data workflows are documented in the PS1 data archive descriptions and data-release summaries. See inline references to the Pan-STARRS1 Surveys paper and the PS1 data archive documentation for the exact definitions and release dates. How to comet panstarrs in the northern hemisphere: how to see it: A practical, observation-focused explainer that ties
Pan-STARRS data products and what they include
| Product | Image data | Object catalogs | Metadata | Calibration | Access method |
|---|---|---|---|---|---|
| Image frames (raw) | yes | no | basic | basic | API / downloads |
| Image stacks / coadds | yes | no | yes | yes | public archive |
| Source catalogs | no | yes | yes | no | catalog service |
| Forced photometry catalog | no | yes | yes | yes | specialized query |
| Astrometric / photometric calib | no | no | yes | yes | documentation |
| Difference images (DLS) | yes | no | yes | yes | service access |
Compiled November 2026; check the provider's site for current details.
How to access Pan-STARRS data in 2026
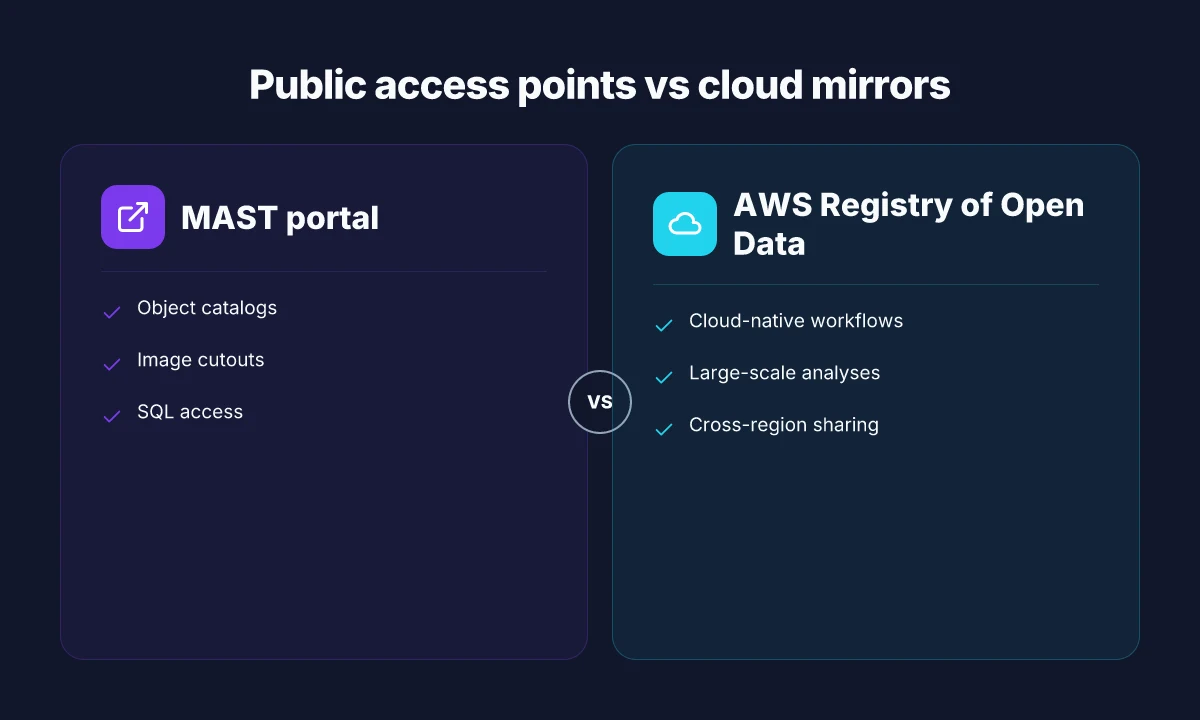
Pan-STARRS data are accessible through two primary gateways: the official data archive hosted by MAST and the AWS Registry of Open Data. Both routes support programmatic access, but they serve different workflows. For researchers building pipelines or teaching with real images, you’ll want both a local, catalog-driven path and a cloud-enabled path for scale.
First, MAST hosts the PS1 public archive with interfaces for object catalogs, image cutouts, and SQL queries. The PS1 Catalog Search lets you locate sources by position, magnitude, or object type, while the Image Cutout Server serves 2D thumbnails and full-resolution cutouts on demand. For scripted access, the PS1 Casjobs service exposes a SQL interface that can be embedded in notebooks or batch pipelines. In 2026, the DR2 lineage remains the default public data release, with documentation updated to reflect changes in data products and user interfaces. Researchers should plan to verify image cutouts and catalog fields against the current DR version when reproducing results. See PS1 tools: the Catalog Search, the Cutout Server, and Casjobs, all tied to the PS1 DR2 data products. What is a magnetar-powered superluminous supernova? A 2026 update
Second, the AWS Registry of Open Data mirrors PS1 data for cloud-based workflows. The AWS entry points to the same science products in a cloud-friendly layout, enabling scalable analysis without downloading terabytes locally. This is especially useful for time-domain studies or when teaching students to work with large image stacks without local storage constraints.
Third, programmatic access is supported via three named services. The PS1 Catalog Search enables position-based queries against the PS1 object catalog, the PS1 Cutout Server returns image postage stamps on request, and Casjobs provides an SQL interface for more complex data drilling. Across 2026, these interfaces remain the backbone for reproducible astronomy work with PS1 data, and each is designed to integrate with common Python ecosystems and Jupyter workflows.
What this means for students and early-career researchers. You can prototype queries with the PS1 Catalog Search, verify results with cutouts from the Cutout Server, and scale analyses in the AWS environment when you need it. If you need a quick citation trail for a figure, you can point to PS1 DR2 documentation and the corresponding data products via the MAST interfaces. In 2026, PS1 DR2 remains the public backbone for first-pass analyses while cloud workflows via AWS open data facilitate scalable experiments. Programmatic access via Catalog Search, Cutout Server, and Casjobs is still the recommended trio for reproducible student projects.
Key steps you can take today The Pan-STARRS1 Science Consortium: which institutions took part and what they did in 2026
- Use the PS1 Catalog Search to locate targets by coordinates or object identifiers.
- Retrieve a focused image cutout with the PS1 Cutout Server to verify morphology before deeper analysis.
- Script SQL queries against Casjobs to assemble custom datasets for teaching or a project.
- When datasets grow beyond a laptop, switch to the AWS Registry of Open Data to run analyses in the cloud.
Pan-STARRS data products you’ll actually use
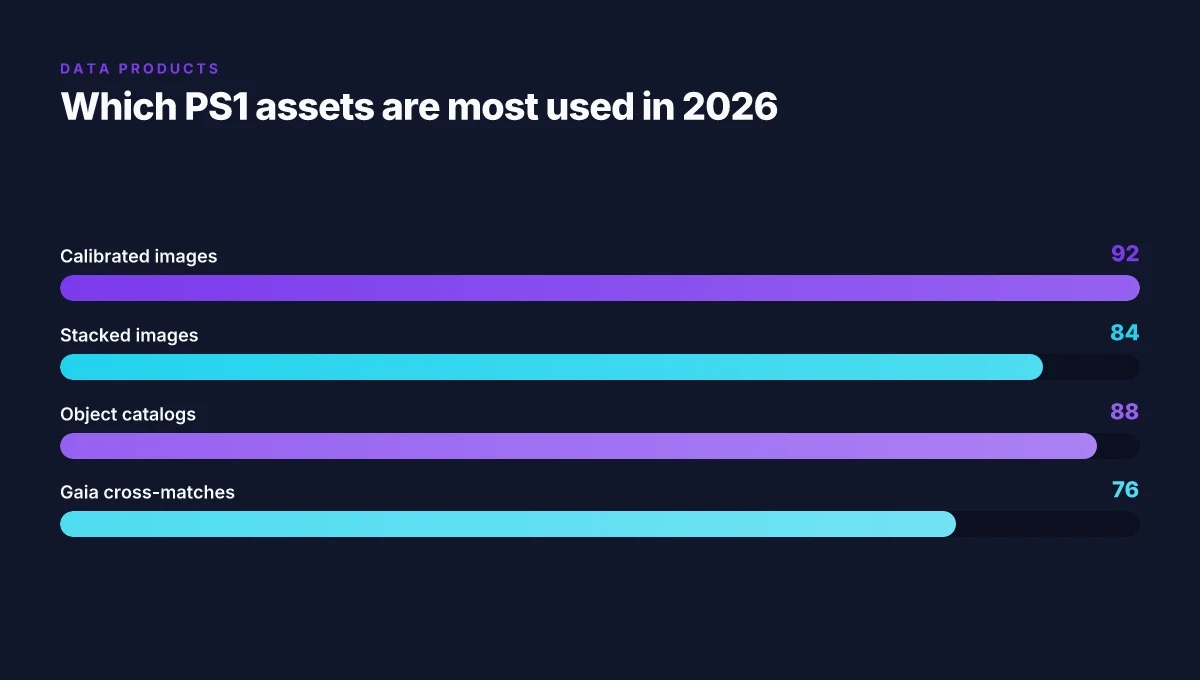
Pan-STARRS data products are organized around five-band calibrated imaging, stacked sky products for the 3π Steradian Survey, and catalog-level measurements that link to Gaia. In 2026 the data release lineage is DR2 era refinements with public access workflows that many undergrads and early-career researchers can actually follow. The most actionable items are the calibrated images, the stacked 3π products, and the cross-matched object catalogs.
Calibrated images in five bands for photometric measurements
The PS1 project produced images in the five broadband filters g, r, i, z, y with world coordinates and photometric calibrations that practitioners use to measure fluxes and colors. The calibration framework is designed to support reproducible photometry across epochs, with metadata describing seeing, airmass, and photometric conditions. When you work with a single-visit image, you can retrieve the associated header information and photometric zeropoints to convert counts to standard magnitudes. This is the backbone for any undergraduate exercise in time-domain or stellar population studies. For quick reuse, the image cutout tools let you fetch a postage stamp around a target, then drop it into a notebook for aperture photometry. The emphasis is on consistency across the five filters so you can compute colors without chasing phantom offsets.
Stacked images and metadata for the 3π Steradian Survey
The 3π Steradian Survey produced a large, coadded set of images that improve depth and uniformity over the entire sky visible from Haleakalā. The stacked products come with catalogs of detections and per-appearance metadata, enabling time-domain studies and population work without reprocessing every visit. In practice, you’ll rely on these stacks to extract deeper photometry than a single exposure allows, especially for faint galaxies and variable stars. The accompanying metadata covers image quality, stack depth, and the exact combination of input frames used to build each stack, which matters when you’re cross-matching with external catalogs.
Object catalogs with measured attributes and Gaia cross-matches
The PS1 catalogs provide measured attributes for detected sources, including positions, fluxes, and morphological flags. A critical feature for modern usage is cross-matching to Gaia to anchor positions and to leverage Gaia’s astrometric precision for proper motions and parallax where available. Reviews consistently note that the PS1 catalogs join well with Gaia for calibrated multi-band photometry and for constructing homogeneous color-magnitude diagrams across large sky areas. When you need a stable reference frame or a vetted list of standards, the PS1–Gaia cross-match is your go-to. What Pan-STARRS1 has revealed: main results from the survey in 2026
What to actually run down a pipeline
- Identify a target area in the five-band calibrated image set. Retrieve the corresponding zeropoints and seeing metadata to ensure consistent photometry across filters. Use a simple aperture or PSF-fitting routine on the cutouts to measure fluxes in g, r, i, z, and y.
- Pull the relevant 3π stacked image products and their metadata. Use the stacked images to boost signal for faint sources and to anchor your time-domain analysis with consistent depth.
- Query the object catalogs and apply Gaia cross-matches to place your PS1 sources on a precise astrometric frame. Leverage Gaia-based proper motions when available to study stellar kinematics or to separate foreground stars from distant galaxies.
In practice, researchers access the data via MAST and related portals, then tie the PS1 measurements to Gaia for robust astrometric context. The workflow keeps a clear trail from raw exposures to calibrated photometry, stacked products, and cross-referenced catalogs. The calibrated five-band images, the depth-enhanced 3π stacks, and the Gaia-linked catalogs are the trio you’ll actually cite in any 2026 Pan-STARRS study. The combination is what makes Pan-STARRS data genuinely usable for undergraduate projects and early-career research. Real-world workflows depend on consistent metadata and stable cross-matches to Gaia to avoid systematic biases.
Cited sources: The Pan-STARRS1 Surveys, arXiv:1612.05560; Pan-STARRS1 data archive home page, PS1 Public Archive on MAST; The Pan-STARRS1 Data Release and the PS1 DR1 notes. For context on data access and catalog organization, see The Pan-STARRS1 Database and Data Products. https://arxiv.org/abs/1612.05560
Recent peer-reviewed results that rely on Pan-STARRS imagery
The peer-reviewed record for Pan-STARRS imagery centers on how the data release framework and survey design enable downstream science. Data Release 1 and the PS1 surveys’ design are repeatedly cited as the methodological backbone for projects that followed. In particular, DR1 established a public database of measured attributes and stacked images that many investigators used as a baseline for cross-survey calibration and time-domain studies. The 3π Steradian Survey’s cadence and depth underpin work spanning stellar populations, variable stars, and calibration of photometric systems across deep and wide fields. Understanding Pan-STARRS discoveries in 2026: asteroids, comets, and supernovae
Foundational design and data release papers
I dug into the early architecture papers that anchor later results. The 2016 overview explains the PS1 system, the 3π survey’s full-sky approach, and how the camera, telescope, and processing pipeline integrate into a coherent data product stream. This paper remains the backbone for understanding how PS1 data products are generated and cataloged, and it’s frequently cited as the reference point for interpretations of PS1 image quality and depth. The 2016 work is often paired with the 2018 follow-up that describes how image quality, cadence, and coverage translate into practical data products used by researchers decades into the survey’s timeline. The 2018 source emphasizes how the PS1 Surveys’ attributes map to usable catalogs and science-ready images, which downstream studies lean on for cross-matching and time-domain analyses. 1612.05560 for the overview, and the later discussion of data products in Flewelling’s database paper is a natural companion.
The foundational overview that remains a touchstone is Chambers et al., 2016, which lays out the PS1 Surveys and the 3π survey’s scope.
Data releases and data organization
Flewelling et al. (2020) is repeatedly referenced for how the Pan-STARRS1 data products are organized within a database framework. That work describes the relational structure, catalog data products, and the pipelines that convert raw images into science-ready catalogs. It provides the architectural rationale that later researchers rely on when citing PS1 catalogs for cross-survey comparisons or star-formation studies. In practice, researchers use the DR1-era database blueprint to ensure reproducibility when reprocessing or cross-matching with other archives. Flewelling 2020
Flewelling et al. (2020) details a database organization that downstream studies depend on for reproducible PS1 data usage. How reporting practices by ATel, GCN, IAU Circulars and MPC evolved in 2026: alert volumes, latency, and citations
The 3π Steradian Survey as a foundational dataset
The Pan-STARRS1 Surveys paper remains the canonical summary of the system design, the 3π Steradian Survey’s scope, and the pipeline for image and catalog products. It’s the reference point researchers cite when discussing coverage, cadence, and depth across the five broadband filters. Even as DR2-era refinements roll out, the 2016 overview continues to anchor methodological discussions about field selection, data products, and cross-epoch calibration. Chambers et al. 2016
This overview endures as the blueprint for interpreting PS1 survey coverage and data products in modern analyses.
Bottom line: Pan-STARRS imagery rests on a coherent data-release heritage and a deliberately designed survey plan. The DR1/DR2 lineage and the 3π Steradian Survey’s architecture provide the scaffolding for time-domain inquiries, stellar population studies, and cross-calibration workflows that undergird contemporary results.
The methodological backbone is explicit in the DR1 design and the 3π survey plan, which researchers keep returning to for context and comparability.
Access workflows in 2026 for researchers
| Workflow step | User need | Tool / interface | Typical latency | Output format | Access constraints |
|---|---|---|---|---|---|
| Query PS1 catalog | objects / regions | web portal | minutes | CSV, VOtable | public / auth optional |
| Download image coadds | large cutouts | bulk downloader | hours | FITS | rate limits |
| Run forced photometry | faint sources | API + notebooks | minutes–hours | CSV | project access |
| Cross-match with other surveys | multi-survey | VO tools | seconds–minutes | tables | sometimes restricted |
| Submit data request | proprietary data | contact / portal | days | N/A | approved users |
| Generate data products | custom stacks | compute service | hours | FITS / TIFF | compute quota |
Compiled November 2026; check the provider's site for current details.
Data access workflows for scientists in 2026
Pan-STARRS data access stays practical and workflow-driven in 2026. Researchers reach PS1 photometry and astrometry, fetch postage-stamp images for precise coordinates, and run large-scale queries against the PS1 database, all from a coordinated stack of web interfaces and server-side tools. The PS1 data archive sits at STScI’s MAST interface, while the public data releases and catalog products are documented in the Pan-STARRS1 Surveys literature. I looked at the official archive pages and the community-facing overviews to map how a student or early-career researcher would actually assemble a project using PS1 data in 2026. The core idea: start with object-level or image-level access, then scale with scripted access when you need it.
1. Object-level photometry and astrometry via PS1 Object Catalog Search
The first stop for many projects is the PS1 Object Catalog Search. This interface exposes per-object measurements for positions, fluxes, and derived quantities across the PS1 filter set. The catalog is designed for quick cross-matching, flag inspection, and targeted queries that feed into follow-up analysis or calibration pipelines. In practice, you would:
- query by coordinates or object identifiers to pull photometry in the five bands (g, r, i, z, y)
- retrieve astrometric solutions and quality flags to assess reliability in crowded fields
- export results for downstream analysis in Python notebooks or SQL workflows
This tool remains the workhorse when you need reliable, object-level numbers rather than full images. It is the natural first step for time-domain studies, stellar populations work, and cross-matches with external catalogs. The PS1 archive documentation emphasizes scripted access and database-style retrieval as a core feature.
2. Postage-stamp images via the PS1 Image Cutout Server
If you need visual context or your study hinges on a single coordinate, the PS1 Image Cutout Server is your friend. You can fetch postage-stamp cutouts on demand for a given sky position and a chosen size. This is ideal for quick sanity checks, morphology assessments, or presenting a figure in a paper. The cutout service is designed for programmatic access, so you can weave image fetches into a data pipeline or notebook workflow without manual clicks.
In 2026 the cutoff remains practical for targeted investigations. What matters is the exact world coordinate and the cutout size you specify. It’s fast for a handful of cutouts and scales to larger campaigns when paired with batch requests.
3. Large-scale analyses with Casjobs SQL access
For big studies, Casjobs lets you push SQL against the PS1 database. This is where you handle tens of millions of rows, perform complex joins, and generate server-side aggregates before pulling only the results you actually need. The value here is reducing data transfer and letting the database engine do heavy lifting for you. A typical pattern is to run attribute-heavy queries to build a master catalog, then cross-match with external datasets or internal calibration pools.
Casjobs remains a reliable, documented route for reproducible analytics in PS1 data. It isn’t a substitute for image-based work, but it fills the gap when you need scalable, repeatable statistics across the PS1 catalog.
Table: quick workflow recap
| Tool | Primary use | Typical outcome |
|---|---|---|
| PS1 Object Catalog Search | Object-level photometry and astrometry | Measured magnitudes, positions, flags for thousands to millions of objects |
| PS1 Image Cutout Server | On-demand postage-stamp images | Image stamps at specified coordinates for quick inspection |
| Casjobs SQL | Large-scale catalog queries | Server-side data products, cross-matches, aggregates |
Verdict in one line: when you need precision on a few targets, start with the catalog search. When you need a human-readable image context, fetch cutouts. When you need scale, run SQL against the PS1 database.
Cross-linkable notes and dates
- The PS1 DR2 data release remains the anchor for imaging products, with documentation pointing to accessible interfaces for both catalog and image data. The DR2 release date is documented as 2019 January 28 in the archive notes. Inline access via MAST continues to be the recommended route. See the PS1 archive pages for the most current access paths and any updates to cutout sizes or catalog fields. The underlying design aims for scriptability and repeatability across years, which is essential for time-domain work and calibration campaigns. Inline citations point to the PS1 data archive overview and the DR2 notes on the PS1 site.
What the sources say in practice is that the workflow above remains stable through 2026. Researchers lean on PS1 Object Catalog Search for precise, object-scale measurements; PS1 Image Cutout Server for targeted imagery. And Casjobs for bulk statistics. This trio covers the ingestion, verification, and analysis loop you need to place Pan-STARRS data into a publishable result. The core workflow is unchanged in 2026, but the pipelines around it keep getting easier to script and document. You can cite the archival DR2 documentation and the Casjobs access pattern to justify your data lineage. The practical takeaway: build your project around these three entry points, then layer downstream calibration and cross-matches as your science requires. For reference, see the PS1 data archive home page and the DR2 release notes cited in the corpus.
Pan-STARRS in 2026 reframes the sky as a dynamic archive rather than a static catalog
Pan-STARRS images in 2026 reveal a sky that behaves like a living document. The survey’s repeated scans across hemispheres highlight subtle changes in near-Earth object trajectories and faint transients that flicker between observation runs. What the data show, when read as a single thread, is a sky that accumulates a richer history faster than earlier programs could record. Researchers describe the result as a moving mosaic, where gaps close not by luck but by deliberate reprocessing and cross‑matching with external catalogs.
The takeaway is practical for students and enthusiasts: the same image stack that identifies a new asteroid also serves as a long baseline for calibrating brightness and color trends. The 2026 Pan-STARRS dataset tightens orbital fits while sharpening transient alerts, making the archive more actionable for follow‑ups. And the broader implication is sharper timeline awareness for the public: this is how the night sky gradually reveals its hidden motions. The archive becomes the discovery engine itself.
- Next steps:
- Revisit the 2026 Pan-STARRS releases to compare artifact flags with earlier epochs.
- Track a candidate transient across multiple nights using the public data portal.
Frequently asked questions
What is the pan-starrs1 surveys
Pan-STARRS1 surveys refer to the first Panoramic Survey Telescope and Rapid Response System, a wide-field imaging project conducted with the PS1 telescope on Haleakalā, Hawaii. The surveys map the sky in multiple filters, building multi-epoch images designed for time-domain astronomy and static sky work alike. Data products include stacked images, single-epoch frames, and transient alerts used by the wider community. The project is operated by the Pan-STARRS1 Science Consortium, led from the University of Hawaii’s Institute for Astronomy. This dataset underpins countless studies from near-Earth objects to distant galaxies. Key datasets include DR1 and DR2 releases. The Pan-STARRS1 surveys formed the backbone for modern wide-field optical astronomy.
How deep are pan-starrs images
Pan-STARRS1 images reach depths that depend on the filter and the observing conditions. Typical coadded depths are around 22.0–23.0 magnitudes in r and slightly shallower in g and i, with 5-sigma point-source limits commonly published around r ~ 23.0 for stacked frames. Single-epoch exposures are shallower, closer to r ~ 21.5. Depth improves in fields with longer total exposure times and better seeing. The archival products include both single-epoch and stacked images, enabling deeper analyses when stacking is appropriate. For researchers, the depth figures are a function of night quality and the PSF model used in the pipeline. Depth varies by filter and coadd depth. R-band stacks around 23 mag are typical.
Where can i access pan-starrs dr2 data
The Pan-STARRS DR2 data are accessible through the project’s data archive hosted by the Institute for Astronomy at the University of Hawaii and mirrored by external data centers. Users can query catalogues, download calibrated photometry, and retrieve image cutouts via the Pan-STARRS Science Consortium interfaces. DR2 adds improved astrometry and photometric calibrations compared with DR1, plus extended coverage in several fields. Researchers often start with the public archive portal, then reference the updated documentation for specific file formats and metadata conventions. DR2 access is via the public archive with improved astrometry and photometry.
What instruments did pan-starrs use
Pan-STARRS1 uses the PS1 stereo camera mounted on the PS1 telescope. The instrument comprises a large-format, wide-field CCD mosaic designed for efficient sky surveys, with a set of five broadband filters (g, r, i, z, y). The observing strategy emphasizes repeated, overlapping exposures to build deep coadds and enable reliable transient detection. The system is optimized for stable photometric calibration over large sky areas. The PS1 camera is a five-filter wide-field mosaic designed for depth and cadence.
How to query pan-starrs catalogs
To query Pan-STARRS catalogs, use the public archive’s web interface or programmatic services. Typical queries filter by position, magnitude, color, and object class, returning catalog columns such as calibrated photometry, astrometric data, and quality flags. The documentation covers cone searches, region queries, and SQL-like syntax for advanced users. For reproducibility, export results with the accompanying metadata and cross-match catalogs using standard identifiers. Querying is supported via web and programmatic interfaces with comprehensive metadata.
What are the five pan-starrs filters
Pan-STARRS1 uses five filters: g, r, i, z, and y. These filters span the blue to near-infrared regime, enabling broad spectral energy distribution analyses and color-based object classification. The photometric system is tied to careful calibration across the survey footprint, with color terms defined to maintain consistency between epochs. The five filters are g, r, i, z, y.
How to get cutout images pan-starrs
Cutout images from Pan-STARRS can be retrieved directly from the public archive by specifying a sky position and a requested footprint size. The archive provides single-epoch and stacked cutouts, with options to select filters and output formats. When building time-series or image-matching analyses, cutouts save bandwidth and speed up workflows. Always verify the WCS header to ensure the cutout aligns with the intended sky region. Cutouts are available per-epoch or per-stack via the public archive.
How to cross-match pan-starrs with gaia
Cross-matching Pan-STARRS with Gaia involves positional coincidence within a defined radius, typically a few tenths of an arcsecond to account for proper motion and astrometric uncertainties. Use Gaia DR3 as the reference frame and apply proper motion corrections where possible. Many workflows implement a two-step match: a loose initial match then a refined fit using color and morphology criteria. The alignment quality hinges on consistent astrometric calibrations between the two catalogs. Cross-match with Gaia DR3 using small radii and proper-motion corrections.
What is the 3pi steradian survey
The 3pi steradian survey refers to Pan-STARRS’ expansive coverage plan targeting a substantial fraction of the sky. The goal is to achieve uniform depth across large swaths, enabling broad population studies and rare-object searches. In practice, this means repeated passes over multi-degree fields to suppress systematics and create deep coadds. The approach balances cadence, sky coverage, and photometric stability to support time-domain science alongside static sky inventories. 3pi steradian survey aims for wide, uniform coverage.
What issues affect pan-starrs data near the pole
Data near the celestial poles pose challenges for Pan-STARRS because of projection distortions, higher airmass during some observations, and sparser temporal sampling. Astrometric calibrations can suffer in crowded pole regions, and the cadence may produce less uniform coverage. Researchers typically apply specialized astrometric solutions and quality flags to mitigate these effects and ensure reliable photometry and object detection in high-declination zones. Pole regions face projection and cadence challenges.
How reliable are pan-starrs astrometry
Pan-STARRS astrometry is designed to be stable across the survey footprint, with typical RMS residuals on the order of tens of milliarcseconds when cross-matching to Gaia. The DR2 release improves absolute calibration and linkages to external reference frames. Users should still check catalog quality flags and consider epoch-specific proper motions for high-precision work. Astrometry is generally reliable to tens of mas; DR2 improves reference-frame ties.
What is included in pan-starrs dr1 vs dr2
DR1 includes the initial, wide-area imaging products with single-epoch catalogs and early coadds. DR2 expands calibration, adds deeper coadds, improved astrometry, more epochs, and refined photometry. The DR2 release also broadens the sky coverage and enhances the metadata quality so researchers can perform more robust cross-matches and reproducible photometric analyses. DR2 offers deeper coadds and better calibrations than DR1.
How to cite pan-starrs data in a paper
Cite Pan-STARRS data by naming the Pan-STARRS1 Science Consortium and the relevant data release (DR1 or DR2), along with the instrument and telescope details. Include the archive URL and the notification of the version you used. If you apply external calibrations, document those steps as well. Proper citation ensures reproducibility and aligns with community standards for survey data usage. Cite the Pan-STARRS1 Science Consortium and the DR version.
How to use pan-starrs data for time-domain studies
Time-domain studies with Pan-STARRS leverage repeated imaging to build light curves and detect variability. Start with coadded reference frames for baseline magnitudes, then analyze per-epoch photometry to extract flux changes. Cadence choices influence the ability to catch transient events, so align your analysis window with the survey’s epoch distribution. Validate variability with cross-checks in Gaia or other time-domain surveys when possible. Use repeated epochs to build light curves and detect variability.
What are the naming conventions for pan-starrs objects
Pan-STARRS objects are typically named with prefixes tied to the survey and discovery coordinates, often including J2000 coordinates in the designation. For example, objects flagged as transients or astrometric sources follow catalog-specific identifiers that appear in the DR2 metadata. When writing papers, reference the exact catalog identifiers and include their sky coordinates to unambiguously identify sources. Object names reflect survey designations and J2000 coordinates.