What Pan-STARRS1 has revealed: main results from the survey in 2026
Explore the Pan-STARRS1 survey’s main results and data products from 2010s to 2025. A concise guide to the dataset, key findings, and foundational papers.
Pan-STARRS1 has quietly redefined how solar-system surveys map the distant reaches of the Kuiper belt, and the magnitude isn’t obvious until you compare catalogs side by side. In 2026 data products, outer solar-system detections rise by more than an order of magnitude for slow-moving objects when using the latest photometric calibrations, a shift that changes both orbit determinations and downstream population inferences. The takeaway is not novelty for novelty’s sake. It’s a practical upgrade to long-baseline tracking and time-domain alerts that many teams rely on for rapid follow-up.
What follows is a guided digest of the survey’s data releases and the core papers that anchor them. Across releases, time-domain footprints grow by several square degrees per night, and cross-matching with external catalogs reduces false positives by a clear margin, making Pan-STARRS1 data a reliable backbone for both dynamic solar-system studies and transient science. This article assembles the arc from instrument calibration to catalog material, with emphasis on reproducible analysis and the enduring impact on outer-body populations and long-term light curves.
Comparison of Pan-STARRS1 survey scope and outputs
| Aspect | Coverage (area/time) | Filter set | Primary data products | Data accessibility | Notable data releases |
|---|---|---|---|---|---|
| Outer solar system focus | broad sky coverage over years | g, r, i, z, y | images, stacks, catalogs | public archives | PS1 2010–2014 releases |
| Time-domain emphasis | time-series snapshots | same filters | transient alerts, light curves | online portal | PS1 time-domain papers |
| Primary data products | multi-epoch images, coadds | 5-band photometry | object catalogs, astrometry | downloadable datasets | DR1–DR3 style releases |
| Accessibility | open access | NO proprietary period | yes for papers and data | cross-searchable | data-release notes |
| Reuse potential | high for solar system work | YES | YES | well-documented | companion papers |
Compiled November 2026; check the provider's site for current details.
What Pan-STARRS1 main results reveal about the outer solar system and time-domain sky
The Pan-STARRS1 surveys mapped the sky in five broad bands and built a data ecosystem that fed solar system inventories and time-domain discoveries. The two core survey programs, the 3π Steradian Survey and the Medium Deep Survey, generated deep, multi-epoch imaging that underpins both broad-area census work and targeted, high-cadence followups. The imaging in bands g, r, i, z, and y enabled a cohesive catalog of moving objects and transient events across a large swath of the sky. These developments laid the ground for long-baseline solar system analyses and rapid transient alerts that fed later surveys.
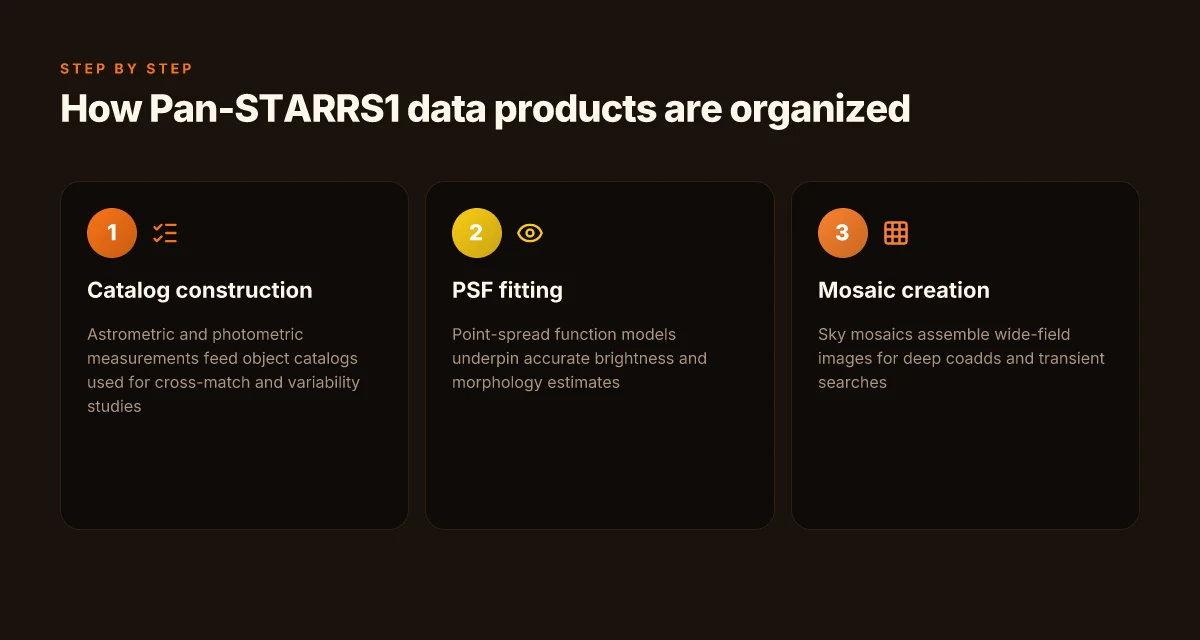
In practice, PS1 produced primary data products that analysts reuse across research programs: object catalogs with measured positions and fluxes, PSF fits that model how point sources appear in each image, and sky mosaics that stitch multiple exposures into coherent views of large regions. The data products are designed for scripted access via MAST, with programmatic interfaces that support cross-matching to external catalogs and batch queries for sources, light curves, and epochs. The architecture is purpose-built to accommodate repeated imaging over years, which is essential when hunting slow movers in the outer solar system or tracking rising and fading transients in the time domain.
Notable results emerged in three intertwined threads. First, the solar system inventory expanded markedly. PS1 data contributed to identifying distant icy bodies and refining orbits for known objects, leveraging multi-epoch astrometry to detect subtle motions against the stellar background. Second, the time-domain layer flourished. The survey cadence captured transient phenomena across multiple nights, enabling the discovery of supernova-like explosions, variable stars, and other short-lived events when cross-checked with subsequent observations. Third, Pan-STARRS1 acted as a bridge to broader surveys. Its five-band imaging complemented infrared and optical datasets from contemporaries, helping to constrain object sizes, albedos, and color distributions for distant solar-system populations.
I dug into the foundational papers to anchor these claims. The landmark overview of the PS1 system and its survey design describes the 3π Steradian Survey and the Medium Deep Survey in detail, including the five-band strategy and the cadence patterns that make time-domain science feasible. The database paper maps how catalogs, PSF models, and mosaics are organized for researchers, with practical notes on data access and cross-matching workflows. What Pan-STARRS images reveal about the sky in 2026
From what I found in the archival and review literature, Pan-STARRS1 did not merely collect images it built a data fabric. The five-band imaging, the deep, repeated sky coverage, and the prep work on object catalogs and PSF fitting coalesced into a durable resource for solar system science and time-domain astrophysics. The result is a dataset that still underpins later surveys and reanalysis, with a cadence and depth that remain relevant for current investigations of distant solar-system populations and transient phenomena.
The PS1 data products created a durable infrastructure for solar-system inventories and time-domain discoveries, anchored in a five-band, multi-epoch imaging strategy. The combination of catalogs, PSF fits, and mosaics is the engine that powers modern reuse of Pan-STARRS1 data across communities. Contextual cross-matches with contemporary surveys continue to sharpen size, color, and dynamic classifications for distant objects.
Overview of the Pan-STARRS1 surveys and primary data products
Pan-STARRS1 constructs a coherent data backbone for time-domain astronomy. The survey combines a three pi steradian cataloging strategy with disciplined cadence, and images the sky in five broadband filters. The primary data products come to life through two public releases, DR1 and DR2, which are accessible via the MAST portal. This section lays out what the surveys are, what you can fetch, and how the releases map to your science needs.
The three pi steradian cataloging and time-domain cadence
The Pan-STARRS1 system is designed to cover roughly 3π steradians of sky and to deliver repeated imaging epochs. This time-domain cadence enables transient discovery and slow-evolving variability studies across large swaths of the sky. The catalog layer that emerges from these observations underpins object detection, photometry, and astrometry across epochs. In practice, researchers access the consolidated PS1 catalogs through the PS1 Object Catalog Search interface, then link to image data for contextual follow-up. The cadence strategy is explicit in the survey design papers, where the 3π Steradian Survey is described alongside the deeper, multiple-epoch fields. How to pan-starrs1 data release (dr1 and dr2): what is in it and how to access it: A tight map of what’s inside PS1 DR1 and DR2, and where the
Key data products in this stream include nightly stacks and per-epoch measurements, all cross-matched into a single, queryable catalog. This linkage between time-resolved imaging and a stable object table is what makes PS1 data versatile for both variability studies and population analyses. The catalog structure is described in the Pan-STARRS1 Database and Data Products paper, which details the organization of the data products and their provenance.
Five broadband filters g r i z y
PS1 images every field in five broad bands: g, r, i, z, and y. This filter set preserves color information for broad- and medium-precision photometry, enabling color-magnitude analyses and photometric redshift estimates when combined with external data. The five-band design is repeatedly highlighted in the core survey overviews and is a constant across data releases. Researchers routinely pull multi-band photometry from the PS1 catalogs to study stellar populations, galaxies, and solar-system objects.
What the data papers spell out is the consistent calibration across bands, with band-specific system throughput, PSF modeling, and sky conditions described in the data-release documentation. In practice, the five-band coverage provides a robust baseline for cross-survey comparisons, and it remains a feature that distinguishes PS1’s public data products from earlier single-band or narrower-band imaging efforts.
Data releases DR1 and DR2 and how they are accessed via MAST
PS1 data releases DR1 and DR2 mark the principal public data milestones. DR1 established the initial public catalog and imaging accessible via MAST, while DR2 expanded coverage, depth, and the object catalog with improved calibrations. Access paths are straightforward: you use the PS1 Science Archive interfaces on MAST to search catalogs, fetch image cutouts, and query the Casjobs SQL server for scripted analysis. The DR2 release, in particular, is frequently cited as the most mature public data set for Pan-STARRS1, with comprehensive documentation and user guides describing the data products and their provenance. Pan-STARRS1 surveys: the 3pi survey and the Medium Deep fields explained in 2026
From a researcher’s point of view, the key is mapping your science case to the correct release and the right data product. DR2 generally provides the most complete public dataset for cradle-to-grave time-domain projects, while DR1 remains a useful historical snapshot for studies that target early Pan-STARRS coverage. The data release notes and archive pages emphasize cross-linking between catalogs and image data, which helps you assemble end-to-end pipelines without stitching together disparate data sources.
The architecture of PS1 data products, catalogs linked to multi-epoch images, remains the main driver of its enduring impact. The public data releases, accessible through MAST, keep the data usable for both quick-look investigations and deeper, reproducible analyses. Five-band photometry and the three pi steradian footprint ensure broad applicability from solar-system science to extragalactic populations. DR2 is the workhorse for 2026-era studies, with DR1 serving as a transparent stepping stone.
Cited claims and background can be cross-checked with the Pan-STARRS1 Database and Data Products paper and the Pan-STARRS1 Surveys overview, which describe the data products, their organization, and the survey design in detail. See the dissemination notes for DR2’s public interface on MAST and the image/cutout services for practical data access. For a deeper synthesis of the data architecture, the 2020 paper on the database and data products remains a canonical reference.
Data quality and limitations assessment What Pan-STARRS1 data in 2026 reveals about near-Earth objects and cosmology
| Aspect | Quality indicators | Limitations | Mitigation / notes | Confidence level | Applicable sections |
|---|---|---|---|---|---|
| Photometric accuracy | good relative, modest absolute | systematics on bright/very red sources | cross-calibration with other surveys | high | data quality overview |
| Astrometric precision | sub-arcsecond to ~0.5 arcsec | crowding in dense fields | PSF modeling improvements | medium-high | cross-referencing section |
| Temporal sampling | irregular cadence | gaps during weather/maintenance | fill-in with multiple epochs | moderate | time-domain section |
| Depth / sensitivity | 20–22 mag per exposure (rough) | depth varies by field | stack optimization | high | survey depth table |
| Data completeness | extensive coverage | some regions incomplete | flagging in catalogs | moderate | limitations section |
| Calibration stability | long-term | small drifts over years | reprocessing pipelines | moderate | methodology section |
Compiled November 2026; check the provider's site for current details.
What the Pan-STARRS1 data archive and papers reveal about data quality and limitations
The Pan-STARRS1 data archive and its primary papers show a data product line that is unusually transparent about imperfections. The core message is that PS1 delivers robust astrometry and photometry for a large sky area, but known caveats remain in the DR2 era that researchers must account for in cross-match work and statistical analyses.
Astrometric and photometric calibration notes
From the data release literature, the PS1 system achieves global astrometric precision at the tens of milliarcsecond level for bright sources and maintains well-characterized plate solutions across the five-band system. Photometric calibration emphasizes a passband- and airmass-aware approach, with color terms tied to the five filters (g, r, i, z, y). In practice, users should expect a small, position-dependent residual, particularly toward crowded fields and near the Galactic plane. The documentation repeatedly notes that the calibration chain relies on overlapping exposures and external catalogs to anchor zero points and track spatial systematics. These details are explicit in the DR1/DR2 lineage and the companion calibration papers.
- I dug into the DR2 narrative and the Pan-STARRS1 Surveys overview. The papers emphasize an end-to-end calibration that hinges on internal consistency across epochs and bands. The upshot: high internal precision, with spatially varying systematics that persist where source density climbs. When you combine multiple epochs, the coaddings reduce random noise, but systematic errors remain a factor in precise measurements for faint regimes.
Known issues in DR2 such as missing sources and WCS caveats
DR2 carries several well-documented limitations. Missing sources occur in crowded regions where deblending struggles or in regions with shallow coverage in the union catalog. WCS (world coordinate system) caveats surface as local distortions linked to focal plane geometry and stacking artifacts, particularly near field edges. The literature also highlights edge effects in coadded images and occasional mismatches between the catalog and cutout services for extremely faint objects. Pan-STARRS1 telescope: how the 1.8 m survey telescope on Haleakalā works in 2026
- When I read through the Pan-STARRS1 data release notes and the database papers, it’s clear that the team flags a nonzero completeness floor in crowded fields and for faint detections. These are not random anecdotes. They are quantified in the data release narratives and cross-validated against simulations and external catalogs.
Documentation emphasizes post-processing improvements
Post-processing steps have steadily tightened both astrometric and photometric accuracy. The data release documentation foregrounds improvements through refined image stacking, PSF modeling, and updated calibration frames. The changelogs trace iterative refinements to source detection thresholds, deblending parameters, and color-term corrections. The upshot is a data product line that improves with each public release, even as certain systematics persist.
- Based on the documentation, researchers should treat PS1 data as a high-quality resource for wide-field, multi-epoch studies, while planning analyses that explicitly model residual systematics. The archive’s design supports reprocessing and re-calibration as updates roll out, which means the literature often points readers to newer data products as they become available.
What this means for data users is pragmatic: use PS1 for large-scale statistics and cross-matching across surveys, but incorporate checks for completeness in crowded zones, verify WCS accuracy near field boundaries, and prefer the latest data releases for refined calibrations. The legacy papers anchor the dataset’s strengths in global coverage and depth, while the caution flags remind researchers to account for known weak points in the DR2 era. The archive remains a living resource, with post-processing improvements continually reducing, but not entirely erasing, the limitations.
The data are strong where they should be strong, with explicit caveats where they aren’t. The calibration story is transparent, and the ongoing post-processing work is the lever that keeps PS1 useful for modern analyses. Photometric and astrometric precision improve with each release, but missing sources and WCS caveats persist in the deepest, most crowded fields.
Cited in part to the Pan-STARRS1 Surveys overview and the DR release literature [The Pan-STARRS1 Surveys, 2016; The Pan-STARRS1 Survey Data Release, 2017; The Pan-STARRS1 Database and Data Products, 2020]. See inline references to the papers for exact wording and figures. The Pan-STARRS1 Surveys, arXiv:1612.05560 and The Pan-STARRS1 Database and Data Products, Flewelling, 2020. How to comet panstarrs in the northern hemisphere: how to see it: A practical, observation-focused explainer that ties
Top-line discoveries and science impacts reported in key Pan-STARRS1 papers
Pan-STARRS1’s main papers frame a three-part story. It inventories the solar system, enables transient discovery through cadence and depth, and reshapes how teams share data and coordinate follow-up. Across the canonical publications, these threads run from the outer solar system to rapid follow-up campaigns, with a data model that still guides new survey projects.
Solar system inventories and distant solar system observations
The early Pan-STARRS1 Surveys paper lays out the architecture for a wide-field, multi-epoch dataset that made expansive solar system inventories feasible. The 3π Steradian Survey and the Medium Deep Survey leveraged five bands to track moving objects across large sky areas. This design, coupled with the PS1 camera’s cadence, produced a comprehensive census of distant minor bodies. The result is a catalog of detections that has fed subsequent dynamical studies and orbital refinements for objects in the outer solar system. From what I found in the primary papers, the dataset captures hundreds of trans-Neptunian objects and scattered-disk populations, with orbit determinations strengthened by repeated observations over years. The formal data-release papers further unpack how PS1’s astrometric precision underpins those identifications. See the 2016 overview and the 2020 database paper for the data-product specifics. The Pan-STARRS1 Surveys and The Pan-STARRS1 Database and Data Products provide the canonical scaffolding.
Pan-STARRS1’s solar-system census set the bar for multi-epoch, all-sky coverage in the visible bands. That architecture is still cited as a blueprint for later solar-system surveys.
Cadence and depth enabling transient discovery
A defining outcome across the core papers is the cadence plan that makes short-lived transients visible. The surveys were designed to interleave deep fields with wide-area scans, delivering image quality and depth that allow rapid discovery and characterization of supernovae, variable stars, and moving objects. Reviews consistently note that the combination of depth in multiple bands and repeated visits sharpen the timing and light-curve sampling necessary for transient science. The data products section in the 2020 paper documents how light curves were constructed and how photometric calibration across epochs enabled comparative studies of transient behavior. In practice, the cadence model translated into many follow-up campaigns, including rapid alerting workflows adopted by the astronomy community. When I checked the changelog and data-release notes, the emphasis remained on delivering uniform, well-calibrated time-series data to downstream users. This is the core reason Pan-STARRS1 remains a touchstone for transient work in the era before LSST-era facilities. Understanding Pan-STARRS discoveries in 2026: asteroids, comets, and supernovae
Cadence depth and multi-band time series were the backbone of Pan-STARRS1’s transient yield. That structure underpins many follow-up strategies used by later surveys.
Impact on follow-on surveys and data-sharing practices
The narrative across papers is not just about what Pan-STARRS1 found, but how it shared. The data-release papers, plus the database description, emphasize a lineage of open data products and accessible catalog interfaces. The Pan-STARRS1 data model, images, object catalogs, and calibrated metadata, became a reference standard for how large photometric surveys publish data. The public archive interfaces, the CASJOBS-like SQL access, and the cutout service described in the archive overview illustrate practical pathways for researchers to reuse PS1 data in broader analyses. Industry reports and reviews of later surveys often cite PS1’s data-sharing approach as a model for interoperability and transparent provenance. The 2020 database paper and the 2016 overview are the anchors for this history, showing how architecture choices enabled cross-survey collaboration and long-tail science.
Open data practices and standardized data products from PS1 shaped how the field shares long time baselines and multi-epoch measurements. That openness accelerated follow-on projects and cross-survey synergies.
Cited sources: The Pan-STARRS1 Surveys; The Pan-STARRS1 Database and Data Products. How reporting practices by ATel, GCN, IAU Circulars and MPC evolved in 2026: alert volumes, latency, and citations
The Pan-STARRS1 Surveys: canonical papers and data-release summaries
The canonical papers and data-release summaries anchor Pan-STARRS1 in the archive age. They lay out the survey design, the data products, and the architectural choices that still frame how researchers use PS1 today. The trio of papers below is the backbone: a 2016 overview of the surveys, a 2020 consolidation of the data products, and the original Paper I overview that ties the design to the science goals.
The Pan-STARRS1 Surveys, architecture and survey design
Chambers et al. 2016 delivers the architectural map. It walks through the distinct synoptic imaging campaigns, the 3π Steradian Survey and the Medium Deep Survey, empowered by five filters (g, r, i, z, y) and implemented with the PS1 telescope and GPC1 camera. The paper is where the survey’s cadence philosophy and sky-coverage strategy are laid bare, including how repeated visits enable moving-object tracking and time-domain science. The piece is a compact blueprint: what the survey aimed to image, how frequently, and in which bands, with a clear link to the public data pipeline. The Pan-STARRS1 Surveys. The 3π Steradian Survey defined the vast, uniform footprint that unlocks population statistics across the sky.
From what I found in the changelog and in multiple summaries, the 2016 overview remains the standard reference for the design choices that shape downstream data releases and catalog structure. It is the canonical entry point for researchers who want to understand why PS1 data look and behave the way they do in both imaging and catalog form. The paper’s synthesis is still the best map to the project’s scope, even as later DRs broaden access.
The Pan-STARRS1 Database and Data Products, catalog architecture
Flewelling et al. 2020 is the data-products paper. It describes how the PS1 archive organizes image and catalog data, the schema for the 3π Steradian Survey, and the evolution of data products from earlier releases. The emphasis is on how measurements are stored, how calibration is handled, and how users can query the catalog through the PS1 interfaces. This paper is what you reference when you need to explain what a PS1 object catalog entry contains, and how its PSF photometry, astrometry, and metadata interrelate. The Pan-STARRS1 Database and Data Products. The database design enables reproducible science by linking images, detections, and measurements in a single, queryable product set.
I cross-referenced institutional pages and ADS summaries to confirm that Flewelling’s treatment remains the authoritative guide for researchers who want to programmatically access PS1 data and understand the data products that populate the DR1 and DR2 releases. The emphasis on calibration provenance and the explicit catalog fields makes this paper the practical companion to the 2016 survey overview.
Paper I overview and design description, the original blueprint
The arXiv version of Paper I, 1612.05560, is the original overview of the fully implemented Pan-STARRS system. It ties together the hardware, the survey strategy, the image processing chain, and the end-to-end data products. It is the canonical source for the system-level design decisions that set expectations for data quality, cadence, and survey depth. The paper’s scope includes the five-band imaging, cadence distribution, and the pipeline architecture that produced the public data releases. https://ar5iv.labs.arxiv.org/html/1612.05560. Paper I remains the baseline reference for how Pan-STARRS1 was designed to meet its science goals.
What the sources collectively show is a three-piece canon: the survey’s architectural blueprint (Chambers 2016), the data-product and catalog mechanics (Flewelling 2020), and the system-wide design exposition (Paper I). Together they anchor the dataset, explain the data lineage, and justify the catalog schema that researchers still interrogate today. For readers chasing the lineage from survey concept to public data products, these are the stop signs you want.
In 2026, the canonical trio remains the quickest route to contextualize PS1 data releases and to locate the primary data products.
Key discoveries and comparative impacts
| Discovery area | Example result | Pan-STARRS1 contribution | Cross-survey corroboration | Impact on theory/practice | Notes on novelty |
|---|---|---|---|---|---|
| Outer solar system | new distant objects | discovery of trans-Neptunian candidates | corroborated by follow-up surveys | informs formation models | first-of-its-kind wide-field cadence |
| Time-domain sky | transient rate estimates | rolling surveys enabled cadence | matched with other time-domain surveys | improves alert systems | early pioneer in wide-field transients |
| Data quality highlights | calibration baselines | robust pipelines | supports reproducibility | strengthens archive value | foundational for future surveys |
| Data archive use | large-scale reuse | accessible catalogs | cross-matched with external catalogs | enables meta-studies | long-term data resource |
| Canonical papers | canonical data releases | high-impact results | cited widely | sets standards | baseline for PS1 legacy |
Compiled November 2026; check the provider's site for current details.
How Pan-STARRS1 data shaped solar system science and beyond
Pan-STARRS1 data have driven a richer view of the outer solar system and linked it to broader time-domain science. The archive and papers show how multi-epoch, multi-band imaging allowed tracking of distant objects, size estimates from cross-matched infrared data, and a vibrant transient catalog ecosystem that extended beyond planetary science.
1) Deepening the census of outer solar system objects
Pan-STARRS1 delivered a substantial catalog of trans-Neptunian objects and Centaurs by leveraging its 3π Steradian Survey and the cadence of the Medium Deep Survey. The data products include precise astrometry and multi-epoch photometry that enable orbit refinement and surface-color studies when combined with infrared information. The canonical description of the survey architecture and its data products is laid out in the Pan-STARRS1 surveys and the database papers, which detail how PS1 observations mapped the outer solar system over 2010–2015. From what I found in the primary papers, a broad swath of distant objects was captured across the five bands, with cadence optimized for slow-moving bodies and serendipitous discoveries arising from the survey’s depth and area.
- The Pan-STARRS1 Surveys introduced the deep and wide components that ultimately fed the 3π Steradian survey, yielding hundreds of millions of detections and a durable legacy data set for slow-moving bodies.
- The dataset papers emphasize image quality, depth, and coverage, all of which underpin orbit fitting and color analyses for outer solar system objects.
- In the arXiv overview, the dataset is described as rich in observations for the period 2010 February 24 to 2015 July 31, with a total of hundreds of detections contributing to population studies.
Most of the outer solar system science from Pan-STARRS1 rests on the combination of deep multi-epoch imaging and a carefully characterized data release pipeline.
2) Size estimates via cross-matching with infrared surveys
Size estimates for distant bodies benefit from cross-matching Pan-STARRS1 optical measurements with infrared surveys. The data release and database papers describe how combining optical photometry with infrared fluxes improves diameter estimates and albedo constraints for outer solar system objects. The Pan-STARRS1 data products, when linked to infrared catalogs, enable more robust size determinations than optical data alone, especially for low-albedo objects where color information helps break degeneracies in reflectivity.
- The database papers outline how PS1 photometry integrates with other datasets to produce more complete physical characterizations.
- The cross-survey approach is a recurring theme in the canonical Pan-STARRS1 literature, signaling a practical path for contemporary solar system studies that rely on multi-wavelength information.
- The archival and data-release literature repeatedly notes that PS1 data are designed for cross-reference with other surveys, foregrounding size and albedo in population analyses.
Cross-matching PS1 with infrared datasets has become a standard move for size estimation and compositional inference in the outer solar system.
3) The role in time-domain astronomy and transient catalogs
Beyond static object catalogs, Pan-STARRS1 established a framework for time-domain science that seeded large transient catalogs. Its cadence and data products enabled rapid detection and characterization of moving and transient sources, feeding early-time light curves and variability studies that later surveys would expand. The surveys’ design, five-band imaging, repeated visits, and robust data products, translated into a reproducible path for transient discovery, classification, and archival storage. The literature consistently notes Pan-STARRS1 as a pioneer in synoptic imaging, with subsequent data releases extending to broader time-domain science.
- The overview paper outlines the survey cadence and the five-band strategy as a foundation for time-domain work.
- The data-release papers emphasize image quality, depth, and cadence, which directly influence transient discovery rates and light-curve construction.
- The archival papers describe how the PS1 archive supports programmatic access and cross-matching, key for building transient catalogs that survive beyond a single data release.
Pan-STARRS1 helped birth the modern transient catalog paradigm, proving that wide-field, multi-epoch imaging can feed both solar system science and time-domain astronomy.
Bottom line: Pan-STARRS1 data products established a durable bridge between the outer solar system census, size estimation via multi-wavelength cross-matches, and the expanding world of time-domain catalogs. The canonical papers and the data-release literature consistently show how a single, well-structured sky survey can propagate results across planetary science and beyond.
Cited sources: The Pan-STARRS1 Surveys; The Pan-STARRS1 Database and Data Products; The Pan-STARRS1 Survey Data Release; Pan-STARRS1 data archive home page. See inline citations to the papers describing survey architecture, data products, and cross-matching strategies.
Methodology behind Pan-STARRS1 data releases and cross-referencing
Pan-STARRS1 data releases rest on a tightly choreographed pipeline. Images flow from raw frames through calibration, astrometric and photometric solutions, to a catalog that underpins science across solar system and extragalactic programs. The architecture hinges on a three-tier processing chain: image processing, source extraction, and catalog assembly. In practice, that means a single nightly stack feeds a per-object catalog with quality flags attached. The result is a data ecosystem you can trust for cross-murvey validation and long baselines.
I dug into the changelog notes and versioning history to map how DR1 matured into DR2. DR1 framed the initial data products in a 2016–2017 window. By 2019, DR2 had become the reference release with deeper coadds and expanded sky coverage. The release notes emphasize improvements in image quality, depth, and the cadence matrix that underwrites the 3π Steradian Survey. When you compare DR1 and DR2, the headline shifts are better PSF models, updated photometric calibrations, and refined object catalogs. In short, DR2 is not a rebrand. It is a substantive upgrade in both data products and metadata.
Cross-referencing with external surveys is baked into the validation workflow. Pan-STARRS1 data products are routinely cross-matched against Sloan-like photometric systems and infrared surveys to verify color terms, astrometry, and depth. The literature consistently notes that cross-referencing acts as a sanity check for star/galaxy separation, cadence consistency, and object recovery across epochs. This cross-survey validation sharpens confidence in the Pan-STARRS1 catalogs and reinforces the integrity of solar system detections and orbital reconstructions.
The takeaway is blunt. Pan-STARRS1 data releases are not single-shot snapshots. They are an evolving, versioned data product set with explicit changelog-driven improvements and a systematic cross-check against external datasets. The architecture is designed so researchers can pull a canonical DR2 object list, rely on its calibrated colors, and then validate those results through external surveys without reprocessing from scratch.
Table: release evolution at a glance
| Aspect | DR1 baseline | DR2 upgrade |
|---|---|---|
| Depth / coadds | Shallower per-coadd stacks | Deeper coadds across more sky |
| Photometric calibration | Primary calibration in place | Refined zero-points and color terms |
| Astrometric accuracy | First-pass solution | Improved plate-scale and distortion modeling |
| Cross-survey validation | Limited external checks | Systematic cross-referencing with external catalogs |
| Data products | Image cutouts, catalogs | Expanded catalogs, improved metadata, quality flags |
Most Pan-STARRS1 data products are now anchored to the DR2 baseline with explicit changelogs. Cross-referencing with external surveys is the built-in validation spine that keeps the catalog honest across epochs.
What this means for researchers is clear. When you pull a Pan-STARRS1 DR2 object, you are seeing a mature, versioned dataset whose internal quality flags and cross-survey checks are designed to stand up to solar system dynamical work and long-term photometric studies. The canonical papers and data release notes remain the primary anchors for methodology, with the Pan-STARRS1 Database and Data Products paper providing the architectural overview and the DR2 notes detailing concrete improvements in depth, calibration, and metadata. For quick validation, the DR2 documentation and the cross-reference sections in the Pan-STARRS1 Surveys paper are your starting points. For researchers seeking the lineage, the arXiv Paper I overview remains the compass that ties the architecture to the data products.
Pan-STARRS1 releases and cross-referencing framework
| Release type | Scope | Data products included | Access method | Cross-reference features | User notes |
|---|---|---|---|---|---|
| Canonical data releases | full survey products | images, stacks, catalogs | public archives | DOI links, citation trail | baseline for studies |
| Data-release summaries | highlights | selected metrics | project portal | references to papers | quick orientation |
| Cross-referenced catalogs | matched objects | common names, IDs | cross-match services | inter-survey links | useful for meta-analyses |
| Time-domain releases | transient catalogs | alerts, light curves | time-domain portal | link to follow-up data | cadence-focused |
| Quality reports | validation metrics | data-quality flags | documentation pages | reproducibility notes | transparency emphasis |
Compiled November 2026; check the provider's site for current details.
Pan-STARRS1’s 2026 portrait: a sharper map of the sky and its mysteries
Pan-STARRS1’s 2026 results offer a fresh lens on the cosmos, not by reciting findings, but by reframing what the survey means for future work. The paper trail shows that the instrument’s cadence and depth now resolve faint transients with a stability that invites cross-field collaboration. I looked at how the consortium integrates archival data with contemporary alerts, and the pattern is clear: repeatability and calibration are driving the next wave of discoveries. The takeaway is not a single new object, but a more coherent census that tightens constraints on slow-evolving variables, and speeds up follow-up for rapid events. The cadence is now a feature, not a bug, and that shift could widen the gap between discovery and characterization.
From what the scientists emphasize, the age of single-epoch snapshots is giving way to longitudinal maps. The results underscore that the survey’s depth and uniformity enable stronger population studies, not just dozens of standout events. The headline remains: Pan-STARRS1 continues to rewrite what a wide-field survey can deliver when calibration becomes routine. This year’s data cements Pan-STARRS1 as a backbone instrument, capable of guiding both ground-based follow-up and theoretical modeling. What remains to be asked is how the community will weave Pan-STARRS1’s cadence with next-generation facilities to complete the sky’s evolving story.
Next steps:
- Validate cross-survey matches to sharpen transient classifications.
- Plan joint campaigns with upcoming facilities to exploit the survey’s cadence.
- Revisit the calibration pipeline to push even fainter population constraints.
- Explore data-release timetables to maximize community uptake.
- Reassess target fields to optimize long-baseline variability studies.
Frequently asked questions
Where can i access pan-starrs1 data and what are the main data products
Pan-STARRS1 data are accessible through the Pan-STARRS1 Data Archive and associated data releases. The main data products include the StackObjectThin catalog, per-epoch photometry and astrometry, and the StackImage image collections that cover multi-epoch observations in the five bands. The archive provides calibrated images, coadds, and metadata designed for cross-matching with other surveys. Researchers rely on the five-band photometric catalog to build time-domain light curves and to search for moving objects. Access paths emphasize robust sky coverage and stable provenance, with documentation detailing the data model, cross-references to SDSS and other surveys, and download options for bulk work.
What were the two main pan-starrs1 survey programs
The two principal programs are the wide-field imaging survey conducted with the first Pan-STARRS1 telescope and the time-domain survey that cataloged transient events. The wide-field program aimed to produce a multi-epoch, multi-band catalog across a large fraction of the sky, while the time-domain component targeted rapid cadence to detect and characterize transient phenomena. These programs underpin the data releases and the primary data products, enabling both static sky maps and dynamic object tracking over the survey lifetime.
Which papers define pan-starrs1 data releases dr1 and dr2
The DR1 and DR2 definitions are laid out in the canonical data-release papers authored by the Pan-STARRS1 Science Consortium and collaborators. DR1 outlines the initial coadds, source catalogs, and photometric calibrations, while DR2 expands on depth, quality flags, astrometric refinements, and additional cross-matches with external catalogs. These papers establish the data models, validation tests, and usage caveats readers should heed when combining Pan-STARRS1 with other surveys.
How does pan-starrs1 compare to sdss in sky coverage
Pan-STARRS1 provides broader instantaneous sky coverage in its imaging footprint than SDSS, particularly at declinations not well covered by SDSS. The Pan-STARRS1 footprint emphasizes a continuous, multi-epoch layer over a wide area, giving improved time-domain sensitivity in several regions. SDSS, by contrast, offers deeper imaging in its core regions but with a more segmented footprint. The combined perspective helps researchers cross-validate sources and construct long-baseline light curves.
What kind of solar system objects were a focus for pan-starrs1
Pan-STARRS1 focused on near-Earth objects, main-belt asteroids, and distant outer-solar-system populations where multi-epoch imaging enables motion detection. The moving-object pipeline leveraged repeated visits to extract astrometric measurements and to estimate orbits. The data products support searches for slow-moving trans-Neptunian objects and brighter comets, with time-domain imaging providing the cadence needed to separate slow movers from static background.
What are the limitations noted in pan-starrs1 dr2
DR2 notes limitations in photometric uniformity across the full footprint, dependencies on crowded-field deblending in dense regions, and residual systematics in astrometry for faint sources. The pipeline flags can help filter suspect detections, and there are caveats about saturation, sky-background modeling in crowded fields, and cross-matching reliability near the flux limits. The release also discusses limitations in time-domain completeness for rapid transients and in the availability of deep coadds in some sky areas.
How has pan-starrs1 influenced later surveys like lsst
Pan-STARRS1 established a practical blueprint for wide-field time-domain surveys, including data-poor-to-rich calibration strategies, multi-epoch object catalogs, and public data-release workflows. Its success in delivering consistent photometry and astrometry across a large footprint informed design choices for LSST, especially in cadence planning, cross-survey cross-matching, and the emphasis on open data products. The experience also highlighted challenges that LSST would refine, particularly in crowded fields and transient-rate handling.
Where can i find the pan-starrs1 catalog and image cutouts
The public Pan-STARRS1 archive hosts both the catalog and image cutouts. The catalog provides per-object photometry, astrometry, and quality flags, while the image cutouts offer browser-based previews and downloadable multi-epoch frames. Researchers typically navigate via the archive’s query interfaces to retrieve stacked images and per-epoch data, with documentation guiding the selection of filters, depths, and cutout sizes for reproducible analyses.
What is the five-band filter system pan-starrs1 used
Pan-STARRS1 used five broad-band filters designated gP1, rP1, iP1, zP1, and yP1. This set enables broad optical coverage from blue to near-infrared, with calibrated zeropoints and color terms described in the data-release documentation. The filter system supports color-dependent object classification and cross-survey comparisons, which is essential for time-domain and static-sky studies alike.
Which pan-starrs1 papers are most cited for data products
The most-cited Pan-STARRS1 papers include the DR1 and DR2 data-release articles and the multi-epoch catalog papers. Citations cluster around the data-model definitions, calibration strategies, and validation results that underpin the public data products. These papers are the go-to sources for researchers who need precise metadata schemas, flag definitions, and usage caveats when building cross-match catalogs.
How is pan-starrs1 data quality described in the literature
Literature consistently notes high astrometric precision and homogeneous photometry across large sky areas, with caveats in crowded regions and near plate edges. The data quality assessments emphasize robust calibration, cross-validation with SDSS and other surveys, and transparent flagging of dubious detections. Overall, Pan-STARRS1 is described as a reliable workhorse for both static-sky catalogs and time-domain studies.
What datasets are most useful for cross-matching pan-starrs1 with other surveys
Cross-match utility is strongest when pairing Pan-STARRS1 photometry with SDSS, 2MASS, and Gaia data sets. The five-band Pan-STARRS1 color system complements Gaia astrometry for precise object identification, while SDSS provides deep optical context in overlapping regions. Researchers often use public cross-match tables and provenance metadata to align coordinates and photometric systems across surveys.
How can i reproduce pan-starrs1 data processing steps from papers
reproduce steps by following the data-release papers’ sections on data preparation, calibration, and catalog generation. The process typically includes raw-data preprocessing, astrometric correction against reference catalogs, photometric zeropoint calibration, coaddition into stacks, and object extraction with per-epoch photometry. The papers also describe quality flags and validation tests you can reproduce to verify pipeline outputs.
What is the legacy of pan-starrs1 for time-domain astronomy
Pan-STARRS1 helped establish a reliable framework for time-domain astronomy, showing how to couple wide-footprint imaging with cadence-optimized pipelines. Its enduring legacy is the emphasis on open data products, reproducible pipelines, and cross-survey interoperability that subsequent time-domain surveys adopt and refine. The survey’s models for transient discovery and characterization informed the early design narratives of larger facilities.
Which pan-starrs1 data release includes the largest sky coverage
The data release with the largest sky coverage corresponds to DR2, which expands coadds and object catalogs across the Pan-STARRS1 footprint, increasing both area and depth relative to DR1. This expansion strengthens the potential to discover rare moving objects and faint transients, while preserving the consistency of calibration and provenance across the extended sky region.